1234567891011121314151617181920212223242526272829303132333435363738394041424344454647484950515253545556 |
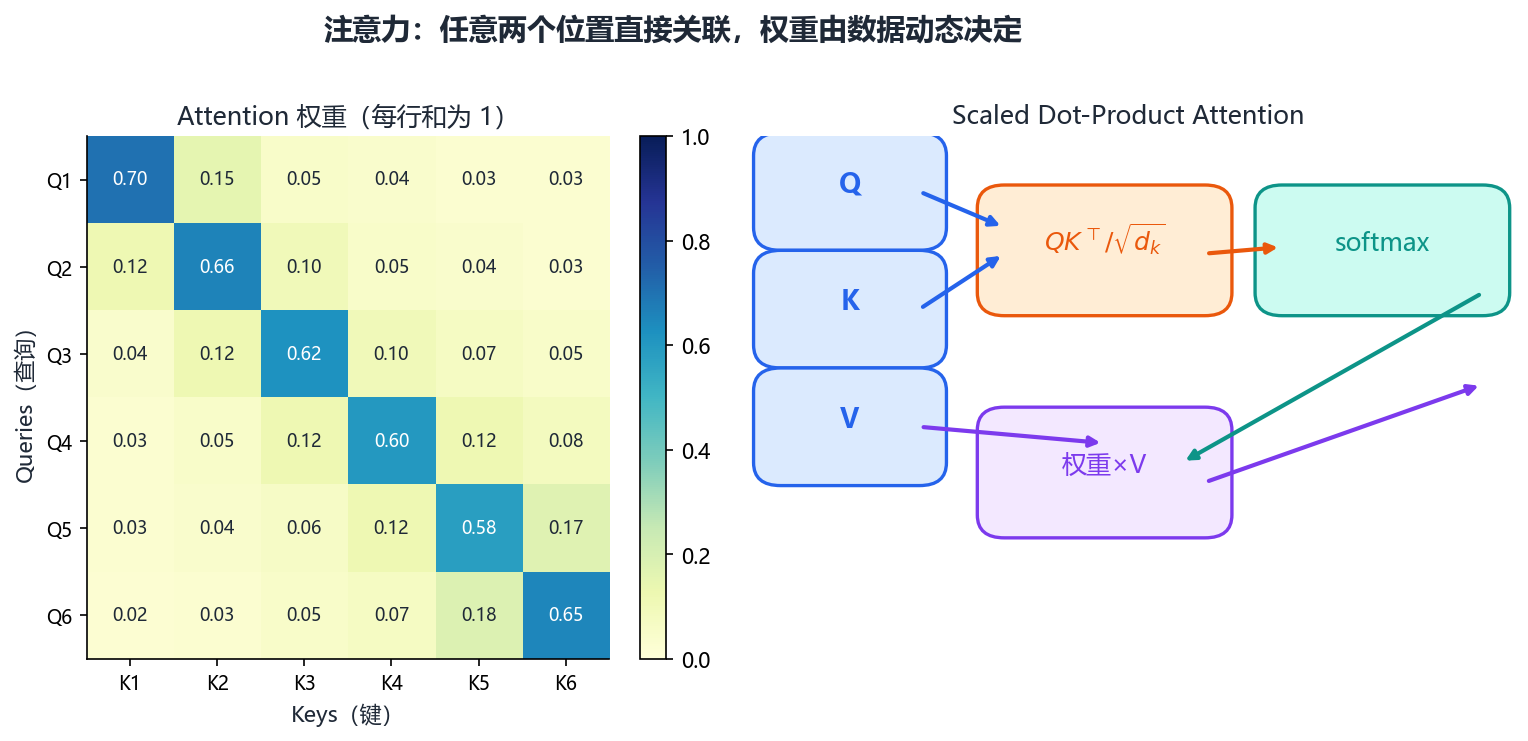
"""演示17: 注意力机制 — 全局关联的"聚光灯"。

手写 scaled dot-product attention:
Query 与 Key 做点积 -> softmax 归一化 -> 加权求和 Value。
用一句话(3 个词)的简单向量演示: 每个词如何"关注"其他词。
"""
import os
import numpy as np
import matplotlib.pyplot as plt
from figure_style import figures_dir, configure

configure()

OUT = figures_dir()
os.makedirs(OUT, exist_ok=True)


def softmax(x):
    e = np.exp(x - x.max(axis=-1, keepdims=True))
    return e / e.sum(axis=-1, keepdims=True)


def attention(Q, K, V):
    """Scaled Dot-Product Attention: softmax(QK^T / sqrt(dk)) V"""
    dk = K.shape[1]
    scores = Q @ K.T / np.sqrt(dk)
    weights = softmax(scores)
    return weights @ V, weights


# 3 个词的随机向量, 构造出明显的关注关系(手工设定使第2个词主导)
words = ["w1", "w2", "w3"]
Q = np.array([[1.0, 0.0], [0.2, 1.0], [0.9, 0.1]])   # 3 个 query
K = np.array([[0.1, 1.0], [1.0, 0.2], [0.0, 1.0]])   # 3 个 key
V = np.array([[0.1, 0.1], [1.0, 1.0], [0.2, 0.5]])   # 3 个 value

out, attn = attention(Q, K, V)
print("注意力权重矩阵:\n", np.round(attn, 3))

fig, ax = plt.subplots(figsize=(6.5, 5.5))
im = ax.imshow(attn, cmap="YlOrRd")
ax.set_xticks(range(3)); ax.set_yticks(range(3))
ax.set_xticklabels([f"K:{w}" for w in words], fontsize=11)
ax.set_yticklabels([f"Q:{w}" for w in words], fontsize=11)
for i in range(3):
    for j in range(3):
        ax.text(j, i, f"{attn[i, j]:.2f}", ha="center", va="center", fontsize=11)
ax.set_title("注意力权重: 每个 Query 如何分配关注(行和为 1)\n"
             "Attention = softmax(QKᵀ/√dₖ)V", fontsize=11)
ax.set_xlabel("Key(被关注)"); ax.set_ylabel("Query(关注者)")
fig.colorbar(im, ax=ax)
fig.tight_layout()
out = os.path.join(OUT, "fig_ai_attention.png")
fig.savefig(out, dpi=150)
print(f"-> {out}")
|