原理公式
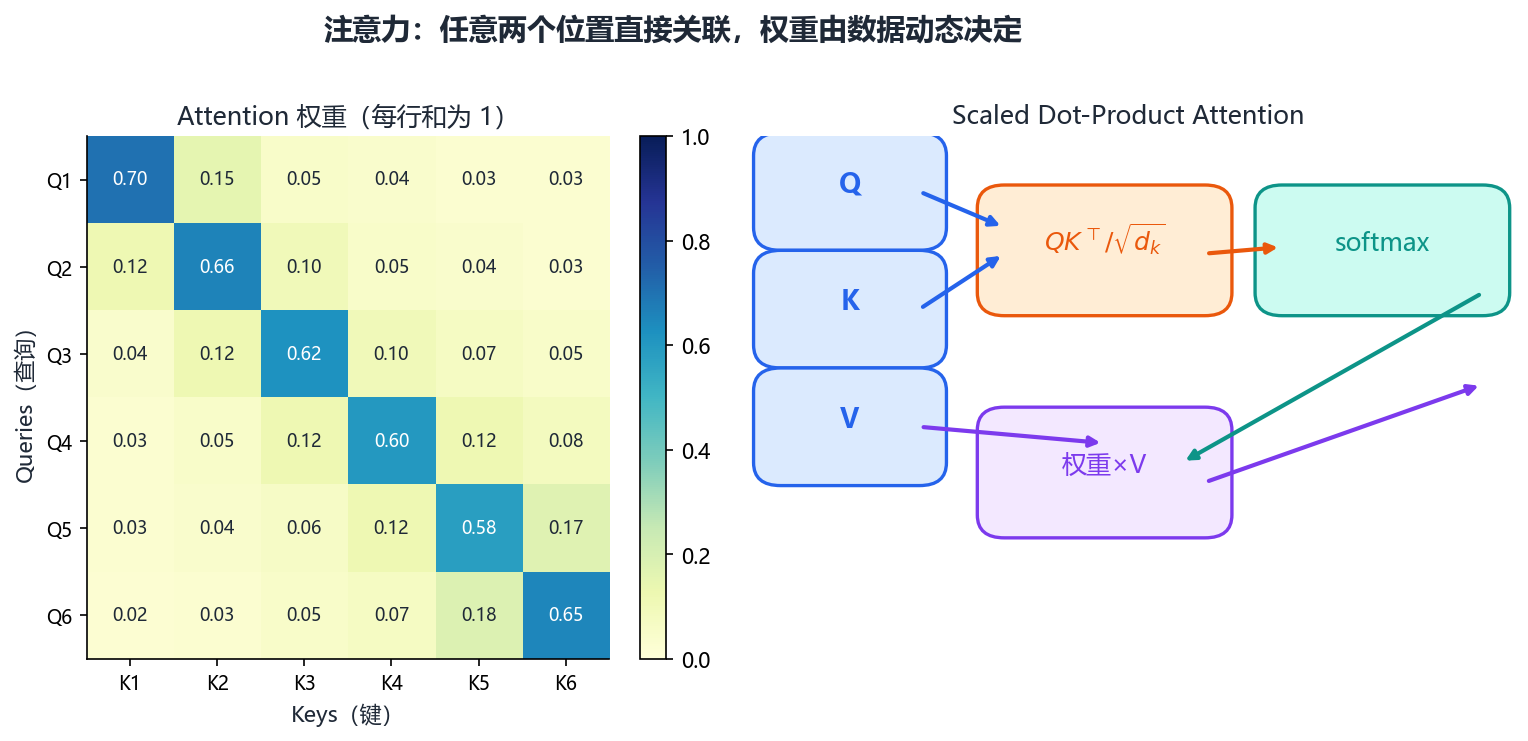
Scaled Dot-Product Attention:输入 Q(Query 查询)、K(Key 键)、V(Value 值):
$$\text{Attention}(Q,K,V) = \operatorname{softmax}\!\left(\frac{QK^\top}{\sqrt{d_k}}\right)V$$
每一步: 1. Q 与 K 点积 → 相关性分数; 2. 除以 √d_k 缩放(防止点积过大导致梯度消失)→ softmax 归一化为权重(行和为 1); 3. 权重加权求和 V → 输出每个位置「该关注谁」。
推导要点:与 CNN 的局部感受野不同,注意力让任意两个位置直接关联(全局), 且权重由数据动态决定——这就是 Transformer「聚光灯」能力的核心。
重难点核心代码(code/demo17_attention.py)
Python
def attention(Q, K, V):
    dk = K.shape[1]
    scores = Q @ K.T / np.sqrt(dk)        # 缩放点积
    weights = softmax(scores)             # 行归一化为权重
    return weights @ V, weights